标签: Python

  • Python3 如何只允许一个脚本实例运行?

    Python3 如何只允许一个脚本实例运行?

    场景需求

    Python3中如何保证同样的脚本在运行时只允许一个运行实例,不允许新建一个脚本重新运行?我们这里使用文件锁的方式,简单方便。下面给出代码实例。

    代码实例

    import sys ,os 
    def lockFile(lockfilepath):
        '''
        :param lockfilepath:文件锁,文件名
        '''
        if os.path.exists(lockfilepath):
            #文件存在,说明脚本正在执行
            logging.critical("×××××× 脚本正在执行中,退出本次调度 ××××××")
            sys.exit()
        else:
            #文件不存在,创建文件,并执行任务。
            logging.info('已开启文件锁 %s',lockfilepath)
            subprocess.getoutput('echo "" > '+lockfilepath)
            return True
    def unLockFile(lockfilepath):
        os.remove(lockfilepath)
        logging.info('已释放文件锁 %s',lockfilepath)

    调用方法

    lockFileName = '/tmp/SCHEDULINGVLAN.Lock'
    func.lockFile(lockFileName)
    #.... do something else ....
    func.unLockFile(lockFileName)
    

    这里lockfileName设定了文件存储位置。

    如果程序意外出错,执行不到程序的最下面释放文件锁的话,永远无法新起脚本进程。

    当然这里也可以使用try / catch的方式来捕捉以外错误,同时释放文件锁。

  • Python微信红包代码实例 微信红包的架构设计

    Python微信红包代码实例 微信红包的架构设计

    Python微信红包算法实例

    #!/usr/bin/env python
    # coding: utf-8
    import random
    # m : 红包个数
    # n : 红包人数
    # packet : 本次抢到的金额 , 所有金额以分为计算
    def redEnvelope(m,n):
        remain = m*100 #剩余金额
        nn = n #剩余人数
        for i in range(1,n):
            if remain == 0 :
                print('已经全部发完了')
            else :
                packet = random.randint(1,int(remain/nn*2))
                nn -= 1
                remain -= packet 
                print('第%d位成员红包的金额为%.2f元 , 余额为%.2f , 剩余%d人未领红包'%(i,packet/100,remain/100,nn))
        print('最后一个成员红包金额为%.2f元'%(remain/100))

    Python调用方法

    redEnvelope(100,4)

    运行结果

    第1位成员红包的金额为45.65元 , 余额为54.35 , 剩余3人未领红包
    第2位成员红包的金额为16.10元 , 余额为38.25 , 剩余2人未领红包
    第3位成员红包的金额为20.98元 , 余额为17.27 , 剩余1人未领红包
    最后一个成员红包金额为17.27元

    概况:2014年微信红包使用数据库硬抗整个流量,2015年使用cache抗流量。

    微信的金额什么时候算?

    答:微信金额是拆的时候实时算出来,不是预先分配的,采用的是纯内存计算,不需要预算空间存储。。
    采取实时计算金额的考虑:预算需要占存储,实时效率很高,预算才效率低。

    实时性:为什么明明抢到红包,点开后发现没有?

    答:2014年的红包一点开就知道金额,分两次操作,先抢到金额,然后再转账。
    2015年的红包的拆和抢是分离的,需要点两次,因此会出现抢到红包了,但点开后告知红包已经被领完的状况。进入到第一个页面不代表抢到,只表示当时红包还有。

    分配:红包里的金额怎么算?为什么出现各个红包金额相差很大?

    答:随机,额度在0.01和剩余平均值*2之间。
    例如:发100块钱,总共10个红包,那么平均值是10块钱一个,那么发出来的红包的额度在0.01元~20元之间波动。
    当前面3个红包总共被领了40块钱时,剩下60块钱,总共7个红包,那么这7个红包的额度在:0.01~(60/7*2)=17.14之间。
    注意:这里的算法是每被抢一个后,剩下的会再次执行上面的这样的算法(Tim老师也觉得上述算法太复杂,不知基于什么样的考虑)。 这样算下去,会超过最开始的全部金额,因此到了最后面如果不够这么算,那么会采取如下算法:保证剩余用户能拿到最低1分钱即可。 如果前面的人手气不好,那么后面的余额越多,红包额度也就越多,因此实际概率一样的。

    红包的设计

    答:微信从财付通拉取金额数据郭莱,生成个数/红包类型/金额放到redis集群里,app端将红包ID的请求放入请求队列中,如果发现超过红包的个数,直接返回。根据红包的裸祭处理成功得到令牌请求,则由财付通进行一致性调用,通过像比特币一样,两边保存交易记录,交易后交给第三方服务审计,如果交易过程中出现不一致就强制回归。

    发性处理:红包如何计算被抢完?

    答:cache会抵抗无效请求,将无效的请求过滤掉,实际进入到后台的量不大。cache记录红包个数,原子操作进行个数递减,到0表示被抢光。财付通按照20万笔每秒入账准备,但实际还不到8万每秒。

    通如何保持8w每秒的写入?

    答:多主sharding,水平扩展机器。

    据容量多少?

    答:一个红包只占一条记录,有效期只有几天,因此不需要太多空间。

    询红包分配,压力大不?

    答:抢到红包的人数和红包都在一条cache记录上,没有太大的查询压力。

    一个红包一个队列?

    答:没有队列,一个红包一条数据,数据上有一个计数器字段。

    有没有从数据上证明每个红包的概率是不是均等?

    答:不是绝对均等,就是一个简单的拍脑袋算法。

    拍脑袋算法,会不会出现两个最佳?

    答:会出现金额一样的,但是手气最佳只有一个,先抢到的那个最佳。

    每领一个红包就更新数据么?

    答:每抢到一个红包,就cas更新剩余金额和红包个数。

    红包如何入库入账?

    数据库会累加已经领取的个数与金额,插入一条领取记录。入账则是后台异步操作。

  • Python3 中如何实现冒泡排序算法?

    Python3 中如何实现冒泡排序算法?

    什么是冒泡排序算法?

    临近的两个元素进行比较,然后互换顺序,一趟走完之后最大的或者最小的元素排在第一个或者最后一个位置(最大或者最小看实际需求),给的的感觉就是一个小泡泡一直冒啊冒,所以有个好听的名字叫冒泡算法

    举个例子,有数组[10, 1, 18, 30, 23, 12, 7, 5, 18, 17],我们使用从小到大的排序方法

    第一趟,外排下标为0,对应的值为10

    内排开始

    ①下标0和下标1的值进行比较。10和1比,发现1比10小,进行互换,内排一次完成,结果是[1, 10, 18, 30, 23, 12, 7, 5, 18, 17]

    ②下标1和下标2的值进行比较。10和18比,10比18小,保持不变,结果是[1, 10, 18, 30, 23, 12, 7, 5, 18, 17]

    ③下标2和下标3的值进行比较。18和30比,18比30小,保持不变,结果是[1, 10, 18, 30, 23, 12, 7, 5, 18, 17]

    ④下标3和下标4的值进行比较。30和23比,30比23大,进行互换,结果是[1, 10, 18, 23, 30, 12, 7, 5, 18, 17]

    ……一直这样紧邻的两个数比下去,第一趟外排结束,结果是[1, 10, 18, 23, 12, 7, 5, 18, 17, 30],我们发现,我们经过了这一次排序,把最大值30送到了右侧

    第二趟,外排下标是1

    内排开始

    ①下标0和下标1的值进行比较。1和10比,1比10小,保持不变,内排一次完成,结果是[1, 10, 18, 23, 12, 7, 5, 18, 17, 30]

    ②下标1和下标2的值进行比较。10和18比,10比18小,保持不变,内排二次完成,结果是[1, 10, 18, 23, 12, 7, 5, 18, 17, 30]

    …………

    ④下标3和下标4的值进行比较。12和23比,23比12小,进行互换,内排四次完成,结果是[1, 10, 18, 12, 23, 7, 5, 18, 17, 30]

    ⑤下标4和下标5的值进行比较。23和7比较,23比7大,进行互换,内排五次完成,结果是[1, 10, 18, 12, 7, 23, 5, 18, 17, 30]

    …………经过一系列排序,结束,结果为[1, 10, 18, 12, 7, 5, 18, 17, 23, 30],这个时候我们把第二大的数据23放到正确的位置

    第三趟

    …………结果为[1, 10, 12, 7, 5, 18, 17, 18, 23, 30]

    …………

    …………

    最终结果为[1, 5, 7, 10, 12, 17, 18, 18, 23, 30]

    至此,排序完成。

    Python3 代码实例

    #!/usr/bin/python
    # -*- coding: utf-8 -*-
    #冒泡排序
     
    def bubble_sort(the_list):
        i = 0
        while i < len(the_list):
            j = 0
            while j < len(the_list)-1:
                print(the_list[j],the_list[j+1])
                if the_list[j] > the_list[j+1]:
                    the_list[j], the_list[j+1] = the_list[j+1], the_list[j]
                j = j+1
                print(the_list)
            print("======"+str(the_list))
            i = i+1
        return the_list
    if __name__ == '__main__':
        the_list = [10, 1, 18, 30, 23, 12, 7, 5, 18, 17]
        print("排序前:" + str(the_list))
        print("排序后:" + str(bubble_sort(the_list)))
    

    运行结果

    排序前:[10, 1, 18, 30, 23, 12, 7, 5, 18, 17]
    10 1
    [1, 10, 18, 30, 23, 12, 7, 5, 18, 17]
    10 18
    [1, 10, 18, 30, 23, 12, 7, 5, 18, 17]
    18 30
    [1, 10, 18, 30, 23, 12, 7, 5, 18, 17]
    30 23
    [1, 10, 18, 23, 30, 12, 7, 5, 18, 17]
    30 12
    [1, 10, 18, 23, 12, 30, 7, 5, 18, 17]
    30 7
    [1, 10, 18, 23, 12, 7, 30, 5, 18, 17]
    30 5
    [1, 10, 18, 23, 12, 7, 5, 30, 18, 17]
    30 18
    [1, 10, 18, 23, 12, 7, 5, 18, 30, 17]
    30 17
    [1, 10, 18, 23, 12, 7, 5, 18, 17, 30]
    ======[1, 10, 18, 23, 12, 7, 5, 18, 17, 30]
    1 10
    [1, 10, 18, 23, 12, 7, 5, 18, 17, 30]
    10 18
    [1, 10, 18, 23, 12, 7, 5, 18, 17, 30]
    18 23
    [1, 10, 18, 23, 12, 7, 5, 18, 17, 30]
    23 12
    [1, 10, 18, 12, 23, 7, 5, 18, 17, 30]
    23 7
    [1, 10, 18, 12, 7, 23, 5, 18, 17, 30]
    23 5
    [1, 10, 18, 12, 7, 5, 23, 18, 17, 30]
    23 18
    [1, 10, 18, 12, 7, 5, 18, 23, 17, 30]
    23 17
    [1, 10, 18, 12, 7, 5, 18, 17, 23, 30]
    23 30
    [1, 10, 18, 12, 7, 5, 18, 17, 23, 30]
    ======[1, 10, 18, 12, 7, 5, 18, 17, 23, 30]
    1 10
    [1, 10, 18, 12, 7, 5, 18, 17, 23, 30]
    10 18
    [1, 10, 18, 12, 7, 5, 18, 17, 23, 30]
    18 12
    [1, 10, 12, 18, 7, 5, 18, 17, 23, 30]
    18 7
    [1, 10, 12, 7, 18, 5, 18, 17, 23, 30]
    18 5
    [1, 10, 12, 7, 5, 18, 18, 17, 23, 30]
    18 18
    [1, 10, 12, 7, 5, 18, 18, 17, 23, 30]
    18 17
    [1, 10, 12, 7, 5, 18, 17, 18, 23, 30]
    18 23
    [1, 10, 12, 7, 5, 18, 17, 18, 23, 30]
    23 30
    [1, 10, 12, 7, 5, 18, 17, 18, 23, 30]
    ======[1, 10, 12, 7, 5, 18, 17, 18, 23, 30]
    1 10
    [1, 10, 12, 7, 5, 18, 17, 18, 23, 30]
    10 12
    [1, 10, 12, 7, 5, 18, 17, 18, 23, 30]
    12 7
    [1, 10, 7, 12, 5, 18, 17, 18, 23, 30]
    12 5
    [1, 10, 7, 5, 12, 18, 17, 18, 23, 30]
    12 18
    [1, 10, 7, 5, 12, 18, 17, 18, 23, 30]
    18 17
    [1, 10, 7, 5, 12, 17, 18, 18, 23, 30]
    18 18
    [1, 10, 7, 5, 12, 17, 18, 18, 23, 30]
    18 23
    [1, 10, 7, 5, 12, 17, 18, 18, 23, 30]
    23 30
    [1, 10, 7, 5, 12, 17, 18, 18, 23, 30]
    ======[1, 10, 7, 5, 12, 17, 18, 18, 23, 30]
    1 10
    [1, 10, 7, 5, 12, 17, 18, 18, 23, 30]
    10 7
    [1, 7, 10, 5, 12, 17, 18, 18, 23, 30]
    10 5
    [1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    10 12
    [1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    12 17
    [1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    17 18
    [1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    18 18
    [1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    18 23
    [1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    23 30
    [1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    ======[1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    1 7
    [1, 7, 5, 10, 12, 17, 18, 18, 23, 30]
    7 5
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    7 10
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    10 12
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    12 17
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    17 18
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    18 18
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    18 23
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    23 30
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    ======[1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    1 5
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    5 7
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    7 10
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    10 12
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    12 17
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    17 18
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    18 18
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    18 23
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    23 30
    [1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    ======[1, 5, 7, 10, 12, 17, 18, 18, 23, 30]
    排序后:[1, 5, 7, 10, 12, 17, 18, 18, 23, 30]

  • 在Python3 Django框架 模板中如何使用条件判断?

    在Python3 Django框架 模板中如何使用条件判断?

    老季在本篇记录一下在Django的开发中,如何在模板中使用if判断条件。

    views.py

    # view 文件
    def func(request):
        ...
        return render(request,"index.html",{
            'current_user':"alex",
            'user_list':['alex','eric',
            'user_dict':{'k1':'v1','k2':'v2'}]
        })

    .html 模板

    # html 文件
    <html>
        ....
    <body>
        <div>{{current_user}}</div>
        <a>{{ user_list.0}}</a>
        # 条件判断
        {% if age %}
            <a> 有年龄<a>
        {% else %}
            <a> 无年龄<a>
        {% endif %}
        # 嵌套条件判断
        {% if age %}
            <a> 有年龄<a>
        {% if age > 16 %}
            <a>老男人<a>
        {% else %}
            <a>小男孩<a>
        {% else %}
            <a> 无年龄<a>
        {% endif %}
        <body>
    </html>
  • Python 登录交换机switch 巡检 拉取交换机配置信息

    Python 登录交换机switch 巡检 拉取交换机配置信息

    场景需求

    前面老季写了一个 PHP如何登录连接TELNET并执行交换机命令类 图文教程 ,最近项目中遇到了要换python3来登录交换机并拉取配置。这里我们直接贴出相关代码使用telnetlib类来登录交换机并拉取配置。

    我们在代码中可以处理交换机拉取配置时,内容过长,出现 --- More --- 需要按空格的场景。并且将所有交换机命令的返回值都进行了返回给调用方法。

    代码实例

    class TelnetClient():
        def __init__(self,):
            self.tn = telnetlib.Telnet()
            time.sleep(0.2)
        # 此函数实现telnet登录主机
        def login(self,host_ip,username,password,port=23):
            try:
                # self.tn = telnetlib.Telnet(host_ip,port=23)
                self.tn.open(host_ip,port)
            except:
                logging.critical('网络连接失败'+repr(host_ip))
                return False
            # 等待login出现后输入用户名,最多等待10秒
            self.tn.read_until(b'Username: ',timeout=1)
            self.tn.write(username.encode('ascii') + b'\n')
            self.tn.read_until(b'Password: ',timeout=1)
            self.tn.write(password.encode('ascii') + b'\n')
            # 延时两秒再收取返回结果,给服务端足够响应时间
            time.sleep(0.2)
            # 获取登录结果
            # read_very_eager()获取到的是的是上次获取之后本次获取之前的所有输出
            command_result = self.tn.read_very_eager().decode('ascii')
            if 'Login incorrect' not in command_result:
                return True
            else:
                return False
        # 此函数实现执行传过来的命令,并输出其执行结果
        def execute_some_command(self,command):
            logging.info('开始执行交换机命令:'+command)
            # 执行命令
            self.tn.write(command.encode('ascii')+b'\n')
            time.sleep(0.2)
            # 获取命令结果
            a = []
            a.append(('--- More ---').encode('ascii'))
            command_result = self.tn.read_very_eager().decode('ascii')
            while True:
                b,c,d = self.tn.expect(a,timeout=1)
                command_result += d.decode('ascii')
                if 0 == b:
                    time.sleep(0.2)
                    self.tn.write(b' \n') #不用\r\n来继续
                else:
                    break
            logging.info('命令执行结果:'+repr(command_result))
            if 'Error:' in command_result :
                logging.critical('执行结果中可能包含错误`Error:`,脚本强制退出')
                sendWxMsg('流量调度系统交换机命令执行出现错误,请及时处理!')
                sys.exit()
            return command_result
        # 退出telnet
        def logout(self):
            self.tn.write(b"exit\n")
            self.tn.close()
    

    多个交换机命令时封装调用(可自行封装)

    # 执行多条交换机命令
    def execSwitchCmd( host , username , password , commands , extra = '1' ) :
        '''
        :param host:主机地址
        :param username:用户名
        :param password:密码
        :param commands:列表命令集
        :param extra: 是否需要执行 system-view , commit 命令
        '''
        logging.info('开始执行交换机命令【'+repr(commands)+'】')
        # return True
        telnet_client = TelnetClient()
        msg = ''
        # 如果登录结果返加True,则执行命令,然后退出
        if telnet_client.login(host,username,password) :
            if extra == 1:
                msg += telnet_client.execute_some_command( 'system-view' )
            for command in commands :
                msg += telnet_client.execute_some_command( command )
            if extra == 1:            
                msg += telnet_client.execute_some_command( 'commit' )
            telnet_client.logout()    
        return msg

    调用方法

    cmd = []
    cmd.append('dis traffic-policy applied-record TO_TrafficCenter')
    res = func.execSwitchCmd(room['host'],room['username'],room['password'],cmd , '0')
    if 'xxxxx' in res :
        # 某些配置在交换机中,做什么处理
        ......

    交换机命令过多时,建议使用\r\n拼接命令并分组

    def centerSchedulingOut95( destination_id , pieces ) :
        # .....
        #.......
        cmd = []
        i = 1
        divided = 12
        tmpCmd = ''
        for policy in policys :
            from_room = getRoomById( policy['destination_id'] )
            if i % divided == 0 :
                cmd.append( tmpCmd )
                tmpCmd = ''
            else :
                tmpCmd += '\r\n' + policy['name'] + '\r\n' + 'UNDO traffic-policy TO_'+from_room['abbr']+' inbound' + '\r\n' + 'traffic-policy TO_'+to_room['abbr']+' inbound' + '\r\n'
            i += 1
            config.cursor.execute("UPDATE center_policy SET status = 2 ,destination_id = %s , update_time=%s WHERE id = %s" , [ destination_id , getNow() , policy['id'] ] )
            logging.info('|----已更改 %s 状态为:使用中,去向机房ID:%s',policy['name'] , to_room['id'])
        if tmpCmd != '' :
            cmd.append( tmpCmd )
        logging.info('|----开始登录调度中心交换机,批量执行调出POLICY命令')
        config.cursor.execute("SELECT * FROM center")
        centerObj = config.cursor.fetchone()
        if len(cmd) > 0 :
            logging.info('|----本次实际调度POLICY规则条数:%s',repr( len(policys) ) )
            execSwitchCmd( host = centerObj['host'] , username = centerObj['username'] , password = centerObj['password'] , commands = cmd )

    我们这里将命令拼接成 \r\n的格式拼接,每12个命令一组,传入到交换机里执行。

  • Python3 半自动使用 ChromeDriver 采集豆瓣图片 并提交到 Chevereto 图床

    Python3 半自动使用 ChromeDriver 采集豆瓣图片 并提交到 Chevereto 图床

    前面我们写了Python 爬虫 抓取豆瓣小组图片 通过api提交入库到 Chevereto 图床,但是现在有些群组需要登录才行,所以我们这里做了一个半自动脚本并使用chromedriver自动登录豆瓣并提交图片到 Chevereto 图床。

    注:老季是Python新手,且本脚本大部分内容来自网络。

    chormedriver下载地址

    http://npm.taobao.org/mirrors/chromedriver/

    Python代码实例

    #!/usr/bin/python
    # -*- coding: UTF-8 -*-
    # 作者:老季
    # 网址:https://www.laoji.org
    #导入所需的库
    import logging
    import random
    import time
    import urllib.request
    import requests , json
    from selenium import webdriver
    # 实例化driver
    # option= webdriver.ChromeOptions()
    # driver = webdriver.Chrome(chrome_options=option)
    driver = webdriver.Chrome('D:\\Downloads\\chromedriver.exe') # chromedirver所在路径
    # 登陆
    driver.get('https://accounts.douban.com/passport/login')
    driver.find_element_by_class_name('account-tab-account').click()  # 模拟点击
    time.sleep(2)
    driver.find_element_by_id('username').send_keys('豆瓣用户名')  # 输入用户名
    driver.find_element_by_id('password').send_keys('豆瓣密码')  # 输入密码
    driver.find_element_by_css_selector("[class='btn btn-account btn-active']").click()  # 模拟点击
    time.sleep(5)
    '''
    TODO:验证码
    '''
    # 获取cookie
    session = requests.Session()
    cookies = driver.get_cookies()
    for cookie in cookies:
        session.cookies.set(cookie['name'], cookie['value'])
    # print(cookies)
    time.sleep(3)
    logging.FileHandler(filename='Selenium_img_douban.log', encoding='utf-8')
    logging.basicConfig(level=logging.INFO,
                        format='%(asctime)s %(filename)s[line:%(lineno)d] %(levelname)s %(message)s',
                        datefmt='%Y-%m-%d %A %H:%M:%S',
                        # filename='F:\\豆瓣下载\\Selenium_img_douban.log', # 日志保存路径
                        filemode='w')
    # 模拟浏览器提交图片
    def submit_img(url):
        submit_url = 'http://tutie.org/api/1/upload/?key='+urllib.parse.quote_plus('f14fe8e8b11c08902a489706d7d99941')+'&source='+urllib.parse.quote_plus(url)
    #    print(submit_url)
        req = urllib.request.Request(submit_url)
        try:
            res = urllib.request.urlopen(req)
            data = json.loads(res.read().decode())
            return str(data['status_code'])        
        except urllib.error.HTTPError as e:
            print(e.read())      
    
    def get_headers():
        '''
        随机获取一个headers
        '''
        user_agents = ['Mozilla/5.0 (Windows NT 6.1; rv:2.0.1) Gecko/20100101 Firefox/4.0.1',
                       'Mozilla/5.0 (Windows; U; Windows NT 6.1; en-us) AppleWebKit/534.50 (KHTML, like Gecko) Version/5.1 Safari/534.50',
                       'Opera/9.80 (Windows NT 6.1; U; en) Presto/2.8.131 Version/11.11']
        headers = {'User-Agent': random.choice(user_agents)}
        return headers
    
    def get(url,group_url, start_page, end_page, params=None):
        '''
        向一个url发送get请求,返回response对象
        :param url: 网页链接
        :param params: URL参数字典
        :return: 发送请求后获取的response对象
        '''
        # 等待一个随机的时间,防止被封IP,这里随机等待0~6秒,亲测可有效地避免触发豆瓣的反爬虫机制
        time.sleep(6 * random.random())
        resp = session.get(url, params=params, headers=get_headers())
        print(resp)
        logging.info(resp)
        if resp:
            logging.info(
                '[get] url = {0}, status_code = {1}'.format(url, resp.status_code))
            resp.encoding = 'utf-8'
            # 这里很重要,每次发送请求后,都更新session的cookie,防止cookie过期
            if resp.cookies.get_dict():
                session.cookies.update(resp.cookies)
                logging.info('[get] updated cookies, new cookies = {0}'.format(
                    resp.cookies.get_dict()))
        else:
            logging.info('[get] url = {0}, response is None'.format(url))
        logging.info('[info] 寻找小组列表地址...')
        logging.info('[get] 已进入小组首页')
        while start_page <= end_page:
            driver.get(group_url + str((start_page - 1) * 25)) # 晒晒你最性感的照片小组
            logging.info('已进入第' + str(start_page) + '页')
            print('已进入第' + str(start_page) + '页')
            # 每一页讨论链接列表
            links = driver.find_elements_by_xpath(r"//tbody/tr/td[@class='title']/a")
            topic_links = {}
            for link in links:
                topic_link = link.get_attribute('href')
                title_name = link.get_attribute('title')
                # 获取的图片以小组话题名称命名
                img_name = title_name.replace('?', '?').replace('\\', '').replace('/', '').replace('"', '').replace(':','').replace('*','').replace('<', '').replace('>', '').replace('|', '').replace('\n', '')
                topic_links[topic_link] = img_name
                topic_num = 0
            for topic_link, img_name in topic_links.items():
                logging.info('进入第' + str(start_page) + '页,第' + str(topic_num + 1) + '话题。')
                topic_num += 1
                driver.get(topic_link)
                # 判断该话题下有无图片
                img_links = driver.find_elements_by_class_name('image-wrapper')
                if len(img_links) > 0:
                    i = 0
                    for img_link in img_links:
                        img_name = topic_links[topic_link] + '_' + str(i)
                        img_src = img_link.find_element_by_xpath('./img').get_attribute('src')
                        print('[get] 话题:' + img_name + ', 图片链接:' + img_src)
                        img = img_src.replace('.webp','.jpg')
                        print('提交图片链接:'+img)
                        submit_img( img )
                        # download_img = urllib.request.urlretrieve(img_src, 'F:\\豆瓣下载\\%s.jpg' % img_name)
                        # time.sleep(3 * random.random())
                        i += 1
                else:
                    print('该标题下无图片')
                img_links2 = driver.find_elements_by_css_selector("[class='topic-figure cc']")
                time.sleep(3 * random.random())
            start_page += 1
            time.sleep(3 * random.random())
        time.sleep(5)
        driver.quit()
    
    if __name__ == '__main__':
        home_url = 'https://www.douban.com/'
        group_url = 'https://www.douban.com/group/481977/discussion?start='
        get(home_url , group_url, 0, 10000)
    
  • Python3 Django admin后台中设置某个字段可以选择显示H5自定义颜色的选项卡

    Python3 Django admin后台中设置某个字段可以选择显示H5自定义颜色的选项卡

    场景需求

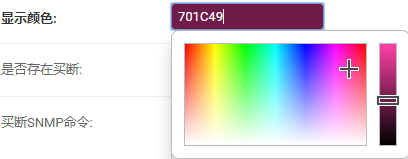
    在Django的项目开发中,如何在后台设置将某个字段使用H5的自定义颜色选择器,实现效果如下图所示:

    可以根据HTML5自定义颜色的设置自定义显示。

    这边我们记录一下如何才能实现

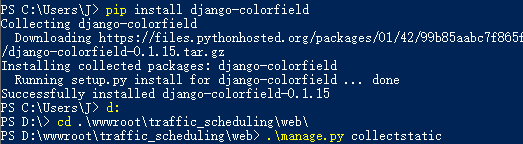
    安装Python扩展

    在终端中执行如下命令

    pip install django-colorfield
    python .\manage.py collectstatic

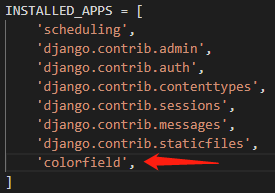
    设置 settings.py

    打开 settings.py ,将 colorfield 添加到 INSTALLED_APPS 配置中

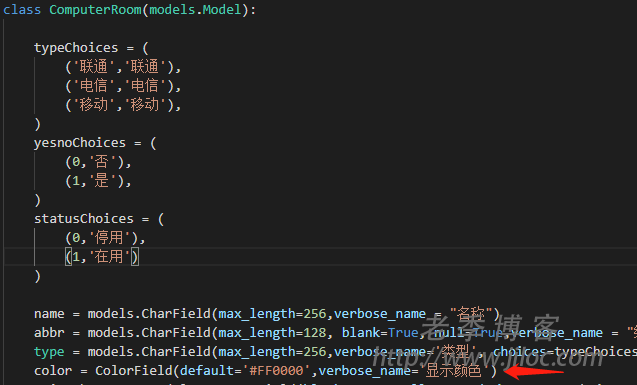
    models.py 中使用

    from django.db import models
    from colorfield.fields import ColorField
    class ComputerRoom(models.Model):
        name = models.CharField(max_length=256,verbose_name = "名称")
        abbr = models.CharField(max_length=128, blank=True, null=True,verbose_name = "缩写")
        type = models.CharField(max_length=256,verbose_name='类型', choices=typeChoices)
        color = ColorField(default='#FF0000',verbose_name='显示颜色')

    然后在Django后台打开对应的模块就可以看到颜色选择器了。

  • Python3 Django 框架中使用脚本预缓存多计算页面

    Python3 Django 框架中使用脚本预缓存多计算页面

    前面几篇文章我们讲述了

    由于我们的数据里已达到百万计,而且页面中有比较多的mysql跨库跨表的计算,在打开页面时会造成时间过长。所以我们需要在Django框架中如何对页面进行预缓存数据。

    本来我们打算使用 request 页面请求的方式,但是项目中需要登录以后才能看到这个页面,所以这条路不考虑。

    但是我们可以将预缓存的数据提前计算好放在Django的缓存中,然后在使用时显示出来。

    注:可以使用文件缓存的方式进行,然后看定期是否自动有新文件生成出来。

    代码实例

    #!/usr/bin/env python
    # coding: utf-8
    ######
    #  调用方法  python .\manage.py flushCaches
    ######
    from django.core.cache import cache
    from scheduling.views import getIndexResult
    import time , datetime , hashlib
    from django.core.management.base import BaseCommand, CommandError
    class Command(BaseCommand):
        def handle(self, *args, **options):
            date =  time.strftime("%Y-%m-%d %H:%M")
            print('开始预缓存首页数据,时间:%s'%date)
            cache_key = hashlib.md5(('index_'+date).encode(encoding='UTF-8')).hexdigest()
            if not cache.get(cache_key) :
                cache.get_or_set(cache_key, getIndexResult(date) ,60*60)

    调用方法

    python .\manage.py flushCaches

    crontab设置

    */1 * * * * cd /data/wwwroot/scheduling/web/ ; /usr/bin/python manage.py flushCaches >> /tmp/flushCache.log 2>&1

    下次我们打开页面时,速度就很快了。

  • Python3 Django框架中如何使用cache缓存代码实例

    Python3 Django框架中如何使用cache缓存代码实例

    场景描述

    在Django开发中,我们在 views.py 里用到了很多的sql查询,很多的跨表跨库显示,而且数据量已达到百万级,为了加快速度显示,这边启用了缓存。

    一开始我们想使用 @cache_page() 来达到缓存的目的,但是这样的缓存没有找到清除缓存的方法。

    所以我们只好使用cache的方式来缓存,这里用时间(年-月-日 时:分)md5后作为缓存的key。

    而且百度一下以后发现,关于django的cache讲述得很少。我们这里做一下简单的笔记。需要说明一下的是 cache.get_or_set ,我一开始以为是如果有这个值就自动获取,但是发现页面任然很慢。所以查了一下官方手册。 cache.get_or_set 手册里面写的是默认是设置新值。大家使用时一定要防止踩这个坑。

    cache.get_or_set(key, default, timeout=DEFAULT_TIMEOUT, version=None)

    If you want to get a key’s value or set a value if the key isn’t in the cache, there is the get_or_set() method. It takes the same parameters as get() but the default is set as the new cache value for that key, rather than simply returned:

    Python3 Django框架中的缓存机制

    views.py 代码实例

    from django.core.cache import cache
    @login_required
    def index( request ):
        if request.GET.get('date_joined_0') is None :
            lastDate = SnmpDiff.objects.values('update_time').filter( type = 'computer_room.snmp_95' ).order_by('-id')[1]
            date_joined_0 =  lastDate['update_time'].strftime("%Y-%m-%d")
            date_joined_1 =  lastDate['update_time'].strftime("%H:%M")
        else :
            date_joined_0 = request.GET.get('date_joined_0').replace('/','-')
            date_joined_1 = request.GET.get('date_joined_1')
        date = date_joined_0 + ' ' + date_joined_1
        cache_key = hashlib.md5(('index_'+date).encode(encoding='UTF-8')).hexdigest()
        # result = cache.get_or_set(cache_key, getIndexResult(date),60*60)
        if not cache.get(cache_key) :
            result = cache.get_or_set(cache_key, getIndexResult(date),60*60)
        else:
            result = cache.get(cache_key)

    现在除了第一次打开慢一点之外,其他时间打开飞快。

  • 如何在Python3 Django 框架中执行自定义python脚本 图文教程

    如何在Python3 Django 框架中执行自定义python脚本 图文教程

    场景需求

    在Django项目开发中,调用一些底层的东西来跑脚本。

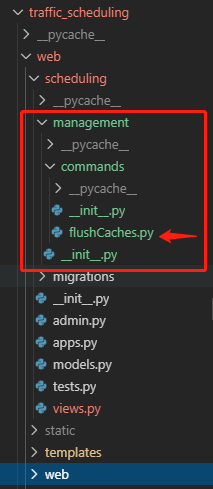
    目录结构

    django入门教程 创建项目(Project)和应用(App)

    这里需要自己新建目录,在应用目录中创建 management/commands 目录,我们这里将脚本名称命名为 flushCaches.py

    脚本代码实例

    #!/usr/bin/env python
    # coding: utf-8
    from django.core.management.base import BaseCommand, CommandError
    class Command(BaseCommand):
        def handle(self, *args, **options):
            # do something ....

    调用方法

    python .\manage.py flushCaches

  • python抓取网站提示错误ssl.SSLCertVerificationError处理

    python抓取网站提示错误ssl.SSLCertVerificationError处理

    问题描述

    python在抓取制定网站的错误提示:
    ssl.SSLCertVerificationError: [SSL: CERTIFICATE_VERIFY_FAILED] certificate verify failed: self signed certificate in certificate chain (_ssl.c:1056)

    解决方式

    在使用请求方法时添加一个参数verify = false就行了,如下:

    response = self.lagou_session.get(url=url,headers=self.header,verify=False)

    或

    res = requests.post(url, data = textmod,  headers = header_dict, verify=False)
  • Python 脚本递归删除 指定文件夹目录下 指定年份 删除所有文件

    Python 脚本递归删除 指定文件夹目录下 指定年份 删除所有文件

    场景需求

    服务器的磁盘被日志等一些老旧数据塞满了,如果人工删除的话需要很长时间。所以这边通过python脚本来做删除。

    本脚本需要在python3中运行。

    功能

    指定文件夹下递归删除所有修改日期在指定年份的文件。

    代码实例

    #!/usr/bin/env python
    # coding: utf-8
    import os , time , datetime , getopt ,sys
    def usage():
        print('usage:%s --input=[value] --output=[value] ')
        sys.exit()
    def listDir(fileDir,year):
         for eachFile in os.listdir(fileDir):
            if os.path.isfile(fileDir+"/"+eachFile):   #如果是文件,判断最后修改时间,符合条件进行删除
                ft = os.stat(fileDir+"/"+eachFile)
                ltime = time.localtime(int(ft.st_mtime)) #获取文件最后修改时间
                file_year = time.strftime("%Y",ltime)
                if int(file_year) == int(year) :         
                    print("删除文件: "+fileDir+"/"+eachFile)
                    # os.remove(fileDir+"/"+eachFile);   #删除文件
            elif os.path.isdir(fileDir+"/"+eachFile) :    #如果是文件夹,继续递归
                listDir(fileDir+"/"+eachFile , year)
    def del_emp_dir(path):
        for root, dirs, files in os.walk(path):
            if not os.listdir(root):
                try:
                    os.rmdir(root)
                except Exception as e:
                    pass
    if __name__ == '__main__':
        options, args = getopt.getopt(sys.argv[1:], '',['path=','year='])
        for name, value in options:
            if name in ('-p','--path'):
                path = format(value)
            elif name in ('-y','--year'):
                year = format(value)
        if 'path' not in locals().keys() or not 'year' in locals().keys() :
            usage()
        listDir(fileDir = path,year=year)
        del_emp_dir(path)
    

    调用方法

    python .\deleteFilesByYear.py --path="D:\Downloads\" --year=2019

WeChat
↑